Two delivery fleets sharing the sky
BlueSky simulation of drones from two delivery companies over Frisco, Texas, each fleet flying its own attention-based multi-agent reinforcement-learning deconfliction policy.
Purdue · West Lafayette, IN
Game-theoretic and learning-based foundations for secure, fair, and decentralized coordination among airspace users.
Purdue’s team, led by Vijay Gupta with co-investigator Mahsa Ghasemi, develops learning and game-theoretic foundations for securing multi-UAV operations. At the individual-aircraft level, the team works on rapid detection of faults and anomalies in vehicle dynamics. At the system level, it develops learning algorithms for security games among multiple UAV owners, methods to detect collusion, digital-twin-based operation, robust information gathering, active communication in multi-agent reinforcement learning, and fair strategic deconfliction. Purdue collaborates with GWU.
Research thrusts
Learning algorithms for Stackelberg games among UAV operators that converge without a trusted, information-rich central coordinator, preserving the privacy of each operator’s costs.
Quantifying how much an agent can gain by deviating from a prescribed learning algorithm, and designing algorithms that remove that incentive.
A statistical framework that detects covert coordination among agents from observed actions alone, with sample-complexity guarantees.
A certifiable, convex test of how faithfully a simplified model bounds the behavior of a real nonlinear system under unknown disturbances.
Game-theoretic sensor placement, scheduling, and target coverage with provable guarantees, and robust selection of information sources.
Multi-agent learning that decides what information aircraft should share, and fair multi-user dueling bandits for strategic deconfliction among operators.
Figures
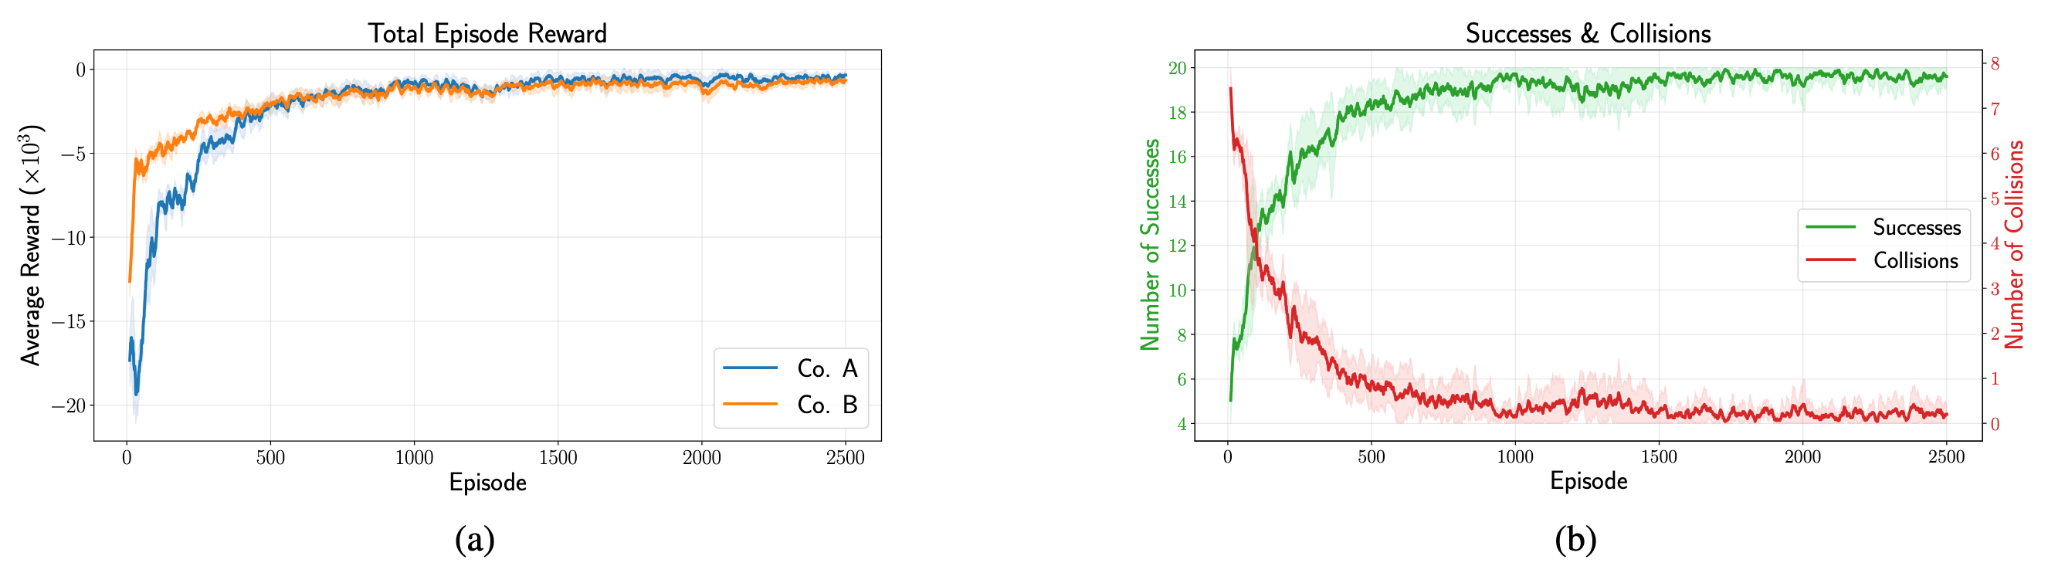
Demos
BlueSky simulation of drones from two delivery companies over Frisco, Texas, each fleet flying its own attention-based multi-agent reinforcement-learning deconfliction policy.
Use cases
Keeping drones from multiple operators safely apart when fleets, policies, and navigation data differ, or are corrupted.
GPS/GNSS degradation and spoofing, and unsafe interactions among heterogeneous fleets and collision-avoidance policies.
Coordinating flight plans, sequencing, and resources among self-interested operators without a single point of failure.
Compromised coordinators, strategic misreporting, collusion, and spoofed arrival information.
People
Publications
12 published or accepted papers
AIAA SciTech Forum, 2026
IEEE Conference on Decision and Control (CDC), 2026Accepted
IEEE Transactions on Automatic Control, 2026Accepted
Automatica, vol. 183, 112648, 2026
Transactions on Machine Learning Research (TMLR), 2026
Transactions on Machine Learning Research (TMLR), 2026
IEEE Transactions on Automatic Control, 2026
IEEE International Conference on Intelligent Transportation Systems (ITSC), 2026
International Conference on Machine Learning (ICML), 2025
Learning for Dynamics & Control Conference (L4DC), 2025
Learning for Dynamics & Control Conference (L4DC), 2025
IEEE Control Systems Letters, 2024